
Legal and Regulatory RAG
A reusable retrieval-augmented generation architecture for legal and regulatory documents, engineered around retrieval accuracy, token cost, model context limits and continuously revised sources.
- ownership
- Sole engineer, end to end
- when
- 2025 - 2026
- org
- Bettrlabs
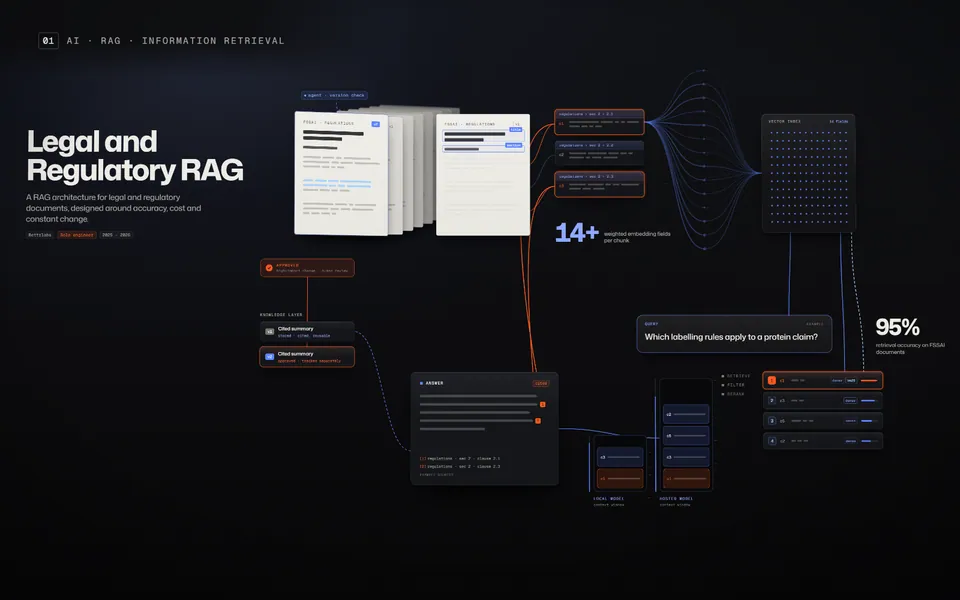
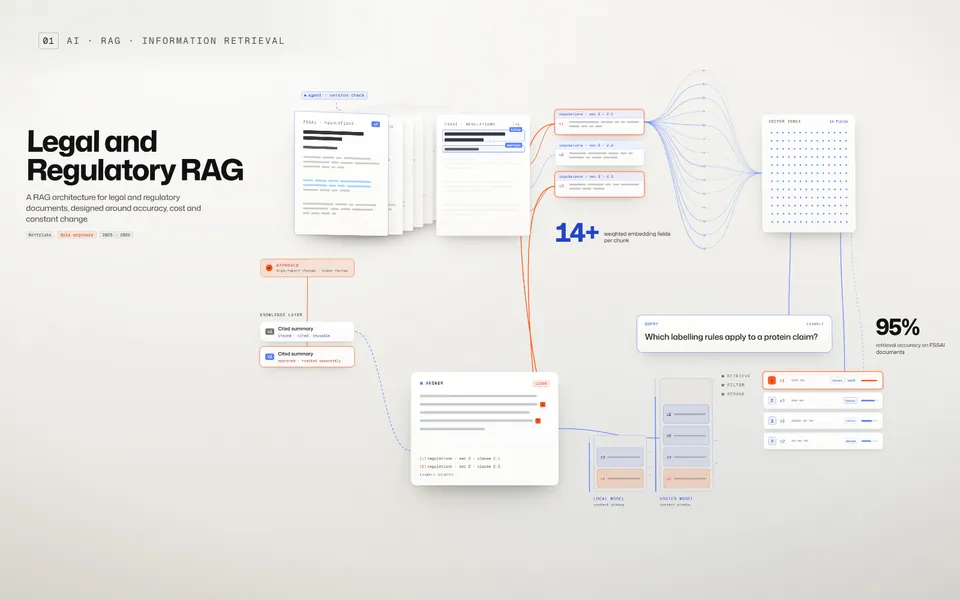
The film, as text: Legal and Regulatory RAG. A reusable retrieval-augmented generation architecture for legal and regulatory documents, engineered around retrieval accuracy, token cost, model context limits and continuously revised sources. Parse: Documents are parsed into their structure automatically, with no manual processing. Context-enriched chunks: Each chunk carries the context around it, so a passage never loses where it came from. Multi-field embeddings: 14+ weighted embedding fields per chunk, instead of one vector. Hybrid retrieval: Dense and lexical search together, then relevance filtering and reranking. Model-aware context: Context is sized to the target model’s window, for local and hosted models alike. Cited answer: The answer cites the passages it was built from. Version-aware knowledge: New versions are tracked separately, and high-impact changes wait for a person to approve. 95% retrieval accuracy on FSSAI documents. 14+ weighted embedding fields per chunk. Sole engineer, end to end, Bettrlabs, 2025 - 2026.
Problem.
Regulatory corpora are long, densely cross-referenced and revised often. Single-vector similarity misses the passages that decide an answer, and passing whole documents to a model becomes expensive at scale.
How it works
- Automated ingestion: parsing, context-enriched chunking, embedding, indexing and retrieval run end to end with no manual document handling.
- Context-enriched smart chunking: each chunk is enriched with document context, and a context-window-aware token allocation algorithm controls how much input goes into the enrichment step.
- Multi-stage hybrid retrieval: dense and lexical (BM25) search across 14+ weighted embedding fields per chunk, fused with weighted reciprocal rank fusion, then filtered for relevance by an LLM and reranked with a cross-encoder.
- Model-aware context selection: retrieved and enriched content is sized to the target model’s context window, across local models and hosted LLM APIs, with token cost designed in from the start.
- Version-aware knowledge layer: cited, RAG-generated summaries are stored as reusable source-of-truth context while newer document versions are tracked separately, which reduces repeat-query token cost.
- Human-in-the-loop versioning: an AI agent detects updated regulatory PDFs and routes the changes for human approval, and approved versions are ingested into the RAG system automatically.
Outcome
In production on labs.new, where it powers the PLM compliance engine and the compliance check, and on bettrlabs.com.
95%
retrieval accuracy on FSSAI documents
14+
weighted embedding fields per chunk
Stack
- Retrieval
- Hybrid retrieval (dense + lexical)
- BM25
- Weighted reciprocal rank fusion
- Cross-encoder reranking
- LLM relevance filtering
- Multi-field embeddings (14+ fields)
- Context-enriched chunking
- Vector databases
- Qdrant
- Pinecone
- Weaviate
- ChromaDB
- ANN vector search
- Models and context
- Local and hosted LLMs
- Embedding models
- Context engineering
- Context-window token allocation
- Version-aware knowledge cache
- Citations
- Automation
- Document parsing
- Ingestion pipeline
- Version-check agent
- Human-in-the-loop approval
- Application
- Python
- FastAPI
- PostgreSQL
- React
- Next.js
- Tailwind CSS